The earlier lessons followed authority from a game process through Windows, driver requests, and physical-memory mappings. The rest of this chapter widens the view to the machine itself: virtual machines, console hardware, chip-level debug interfaces, and emulators. Each gives software a different view of the hardware and a different path from software requests to device effects.
Lesson 1.7 set up a Windows virtual machine for this book’s labs and promised that a snapshot could undo a bad experiment. It did not say how one computer can pretend to be several, or what a snapshot actually stores. A guest network-card write, a R A M, random access memory, address, and a snapshot will make those mechanisms visible. The last section returns to the driver trust boundary from Chapter 12 and follows Windows’ use of the same machinery to protect its own kernel. The next lesson translates one address through both stages digit by digit and shows how software can tell that it is virtualized.
Section: A computer inside a computer.
A virtual machine (V M) is a complete computer made of software: virtual processors, virtual R A M, a virtual disk, a virtual network card, and a virtual screen, convincing enough that an unmodified operating system installs and runs on it. The operating system inside is the guest, and the real computer is the host. The software that creates virtual machines and shares the real hardware among them is the hypervisor, also called a virtual machine monitor.
This is a different kind of virtual machine from the one in Lesson 11.9. Lua’s virtual machine is a program that carries out Lua bytecode, an instruction set that no processor runs in silicon. A hypervisor’s virtual machine offers the same instruction set as the real processor, x86-64, so the guest’s instructions run directly on the real processor, and the hypervisor steps in only when the guest touches something that must stay under the host’s control.
Section: Type 1 and type 2 hypervisors.
In the figure below, each arrow points from a piece of software to whatever it runs on:

A type 1 hypervisor runs directly on the hardware, with no operating system underneath it. Every operating system on the machine runs above it, including the one that manages the others. Hyper-V is type 1: when it is turned on, the hypervisor starts first at boot, and your Windows becomes the root partition, a privileged guest that manages the other guests. Xen and VMware ESXi are also type 1.
A type 2 hypervisor is an application that runs on an ordinary host operating system and relies on it for scheduling, memory, and devices. VirtualBox and VMware Workstation are type 2. Even they need ring 0 for the processor’s virtualization instructions, so each installs a kernel driver alongside its application.
The line blurs in practice. KVM turns the Linux kernel itself into a hypervisor. And on a Windows PC where the Windows hypervisor is already running, as it is whenever memory integrity is on (the last section explains why), VirtualBox and VMware run their guests through Windows’ own hypervisor instead of directly on the processor.
Section: Hardware virtualization: VT-x and AMD-V.
A guest’s kernel expects to run in ring 0, but ring 0 on the real processor already belongs to the hypervisor or the host’s kernel. Running the guest’s kernel in ring 3 instead did not work on x86 for many years, because a few instructions that change the processor’s state quietly behave differently in ring 3 instead of faulting, so the hypervisor never saw them. Lesson 13.4 shows the classic problem instruction and the software workarounds that came first.
In 2005 and 2006, Intel and AMD added hardware support, called Intel VT-x and AMD-V. Both add a separate processor mode for guests. Intel calls it VMX non-root operation, and the hypervisor runs in VMX root operation. Inside the guest mode, the guest gets its own complete set of rings 0 to 3, so the guest kernel runs in its own ring 0, unmodified, and every instruction behaves exactly as the guest kernel expects.
The hypervisor keeps one control structure for each virtual processor, called the VMCS on Intel and the VMCB on AMD. It holds three things:
the guest’s saved state: every register, including the instruction pointer and c r 3;
the host’s state, reloaded whenever the guest stops;
the exit controls: the list of guest actions that must hand control to the hypervisor.
The hypervisor starts or resumes a guest with a V M entry (vmlaunch or vmresume on Intel, vmrun on AMD). The processor loads the guest’s state and runs the guest’s instructions natively, at full speed, until one of the listed actions happens.
Section: What a V M exit is.
A V M exit is the processor stopping a guest and handing control to the hypervisor. The processor saves the guest’s state into the control structure, loads the host’s state, and jumps to the hypervisor’s exit handler, along with a number that says why, the exit reason, and details such as the address involved. The hypervisor deals with the cause, adjusts the guest’s saved state (usually moving its instruction pointer past the instruction it just handled), and enters the guest again. From inside the guest, the instruction simply seems to have taken effect.
Alternative: A V M exit is a service handoff: saved guest state and an exit reason let the hypervisor handle the event before resuming that guest.
Typical causes of an exit:
cpuid, the instruction that describes the processor. On Intel it always exits, so the hypervisor decides what the guest is told about its processor.
Port I/O to a virtual device, such as the in and out instructions from Lesson 12.7.
An access to a guest-physical address that has no usable mapping in the second stage of translation, described in the next section. That is how the hypervisor catches accesses to a virtual device’s memory-mapped registers.
hlt, when a virtual processor has nothing to do and the hypervisor can give the real core to other work.
Interrupts from real hardware, which belong to the host.
Here is one exit, caused by a guest’s network driver writing to a register of its virtual network card:

Exits are expensive. The round trip of exit, handling, and entry takes hundreds to thousands of processor cycles, where an ordinary instruction takes about one. So hypervisors keep exits rare. The guest’s ordinary instructions, its own system calls, and its own page faults never leave the guest, and modern guests use paravirtual devices, virtual devices designed to need few exits. It is the idea Lesson 12.5 called limited direct execution, one level further down: run natively, and trap only what must stay under control.
Section: Two stages of address translation.
Each guest believes it owns physical memory starting at address 0. It cannot: the host’s real memory also starts at 0, and several guests share it. So a guest’s “physical” addresses are really guest physical addresses, and they must be translated once more into host physical addresses, the real addresses of R A M.
In brief: A guest’s physical address is still virtualized; another mapping connects it to the host’s actual R A M.
With second-level address translation (SLAT), the processor does both translations in hardware. Intel calls its version extended page tables (EPT); AMD calls its version nested page tables (NPT). The two stages have different owners:
Stage 1 turns a guest virtual address into a guest physical address, through the guest’s own page tables. The guest kernel writes these tables and switches between them by loading its own c r 3, exactly as it would on a real machine.
Stage 2 turns a guest physical address into a host physical address, through tables that only the hypervisor writes. The guest cannot see them, name them, or change them.

Both stages work a page at a time. The low bits of an address, which pick a byte within its page, pass through unchanged, and each stage replaces only the page number above them. Lesson 13.4 follows one address through both stages digit by digit and counts what the extra stage costs.
Each stage can also refuse. If the guest’s own tables have no entry for a virtual page, the processor raises an ordinary page fault inside the guest, and the guest kernel handles it as it always would. If the hypervisor’s tables have no entry for a guest physical page, as for the network card’s register page in the previous section, the result is a V M exit. Stage-2 entries also carry their own read, write, and execute permissions, and an access succeeds only if both stages allow it.
The second stage is where a guest’s isolation comes from. A guest can write anything it likes into its own page tables, but every address they produce is only a guest physical address, and only the pages the hypervisor maps in stage 2 exist for that guest. Memory that belongs to the host or to another guest has no guest physical address at all, so no instruction the guest can execute is able to name it.
Section: What a snapshot saves and restores.
Lesson 1.7 took snapshots before any experiment. A snapshot can capture a whole running computer because everything that makes up a guest is something the hypervisor owns:
Narration: R A M alone cannot restore an interrupted calculation. A running-machine snapshot also needs the registers and device state that determine what happens next.
The disk. A guest’s disk is an ordinary file on the host. Taking a snapshot freezes that file and starts a new differencing file, the delta, which receives every later write. A read checks the delta first and falls back to the frozen base.
The memory. The guest’s R A M is host memory that the stage-2 tables map. Because the hypervisor knows exactly which host pages those are, it can write all of them to a file, and a snapshot of a running V M includes that file.
The processors and devices. Each virtual processor’s saved state from its control structure, every register including the instruction pointer, plus the state of every emulated device.
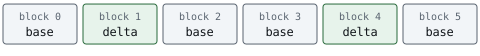
Restore all three, and the guest continues from exactly the instruction it had reached, with its disk exactly as it was. Restoring is quick because nothing is copied back: the hypervisor throws the delta away. Deleting a snapshot is the slow direction, because the delta’s blocks must then be merged into the base.
A snapshot cannot put back anything that left the virtual machine: a file copied to the host through a shared folder, a message already sent over the network (the other end still has it), a change to an online account, or a change to the host itself. It also relies on the hypervisor’s isolation holding. A bug in the hypervisor that lets guest code run on the host, called a V M escape, would put an attacker beyond any snapshot’s reach. Such bugs usually sit in the code that emulates devices; they are rare and valuable, and they are patched quickly. That is why Lesson 1.7 keeps shared folders, the shared clipboard, and U S B passthrough off until they are needed, and why the host’s hypervisor deserves updates as promptly as Windows does.
That is the case for running this book’s Windows labs in a V M. A bug check in the guest’s kernel or a bad driver in the guest (Lesson 12.4, Lesson 12.7) stops only the guest. Debuggers and memory tools, which need broad rights inside the guest, get none outside it. And a restore returns a whole machine, not just one program, to a known state.
A guest is not invisible, though. Software inside it can tell that it is running in a virtual machine, and some anti-cheat systems refuse to run a protected game there; Lesson 13.4 shows how a program finds out.
Section: Windows uses the hypervisor to protect itself.
Lesson 12.4 ended with an uncomfortable fact: kernel code can do anything, so a single exploited driver bug hands an attacker the whole kernel. Virtualization-based security (VBS) answers with the machinery from this lesson. At boot, the Windows hypervisor starts first, and Windows runs above it in two virtual trust levels:
VTL0, the normal world: the Windows kernel, drivers, and every program, in their usual rings 0 and 3;
VTL1, the secure world: a small secure kernel and a few isolated processes, such as the one that guards login secrets when Credential Guard is on.
The hypervisor keeps separate stage-2 permissions for each trust level. VTL1 can ask the hypervisor to change VTL0’s permissions. Nothing in VTL0, not even ring-0 kernel code, can change them, because the stage-2 tables cannot be reached from inside VTL0 at all.

Memory integrity, also called HVCI (hypervisor-protected code integrity), is the VBS feature that uses this arrangement for the kernel’s own code. The code-integrity checks that decide whether a driver is properly signed run in VTL1, where a compromised VTL0 kernel cannot tamper with them. A kernel page becomes executable in stage 2 only after its code passes those checks, and an executable page is never writable.
Suppose an attacker finds a driver bug that lets them write anywhere in kernel memory, the worst case from Lesson 12.4. They can still corrupt data. They cannot write new instructions into a code page, because code pages are not writable in stage 2, and they cannot turn a data page into code, because only VTL1 grants execute permission and it grants it only to signed code. The vulnerable driver blocklist from Lesson 12.7 is enforced whenever memory integrity is on.
Memory integrity is on by default on clean installs of Windows 11 on compatible hardware. It needs the processor’s virtualization support and SLAT, which is one more reason to leave virtualization enabled in the firmware settings. On such a PC, VirtualBox and VMware run their guests through the Windows hypervisor instead of directly on the processor, which can make a lab V M somewhat slower. That is not a reason to turn memory integrity off: Lesson 12.9 lists it among the protections worth keeping.
References: Hyper-V architecture, virtualization-based security, memory integrity and VBS enablement, isolated user mode processes, and the virtual-machine extensions volume of the Intel Software Developer Manuals.