Section: Client and server.
A client is the game program running on a player’s device. It reads the player’s keyboard or controller, draws the world, and exchanges messages with another program over the network.
A server is a program that receives requests from clients and provides a service to them. A game server might keep track of who has joined a match, calculate player movement and damage, and send the resulting positions and health to the connected players. The computer running that program is also often called “the server.” The program can run on a rented machine, on one player’s computer, or beside your client on the same computer during a local test.
Imagine a match where the server calculates movement. It stores a player at (10, 15). The player’s client sends “move north.” The server checks whether the destination is inside the map and free of a wall. If the move is possible, it changes its stored position to (10, 14) and sends that position to the clients. Each client updates the character it draws. If a wall blocks the move, the server keeps (10, 15) and reports that position instead.
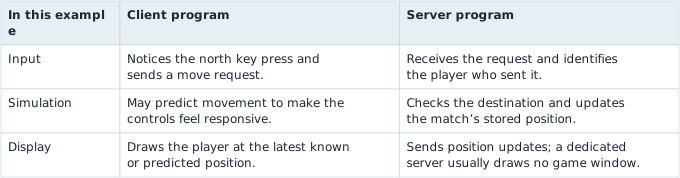
Clarification: Client and server name the programs’ jobs. They do not require two computers: a local test can run both programs on one machine and connect them through loopback.
This is one common arrangement, called a server-authoritative simulation: the server’s accepted position is the one the clients eventually use. Other games give the server a smaller job, such as hosting a lobby or forwarding players’ inputs. A server does not necessarily simulate every part of a game, and the clients do not necessarily hold identical or complete copies of its data.
This chapter follows that message from intent to bytes, from captured bytes to a parsed event, and from one event to a legal session transition. A local chat client and proxy put the pieces together. The final lessons ask how two programs on one computer can exchange equally well-defined messages without using a network socket.
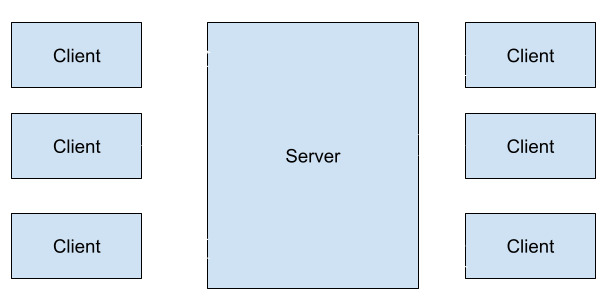

The client’s “move north” is an intent: a request for a change, not the final truth. The reply reports what the server actually accepted. If a wall blocked the move, the reply might still say (10, 15), and the client would correct its display.
These programs have separate memory. Changing a position in the client’s memory does not directly change the server’s stored position. They communicate by sending bytes. A client may display a predicted move while it waits, then correct that display when the server’s reply arrives. The next question is how the reply’s bytes become one complete message at the other end.
Section: Peer-to-peer describes who communicates with whom.
In a peer-to-peer arrangement, players’ programs can exchange messages directly. A lobby service may still introduce them, and a relay may carry bytes when a direct connection is unavailable. Neither service must calculate the match.
A player who hosts a server on their own computer still runs a client/server arrangement if that server accepts movement and sends the final positions. The location of the program does not change its job.
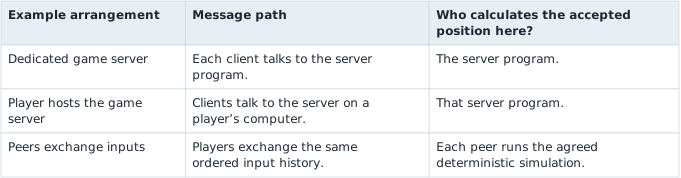
The last row describes one particular design, often called lockstep. Peer-to-peer does not automatically mean lockstep: another design can give one peer responsibility for an object or use different ways to resolve conflicts. Always ask two separate questions: where do messages go, and whose result is accepted? Direct communication alone does not prove which copy owns a gold value.
Clarification: A server is a program with a job. A peer is another participant. Hosting on a player’s computer and exchanging directly between peers describe different choices.
Topology cheatsheet: client/server identifies service roles; peer-to-peer describes communication between participants; authority identifies the accepted result. A topology label alone cannot answer all three questions.
Section: T C P, transmission control protocol, is a stream.
T C P is a common transport for a connection between the two programs. It delivers an ordered stream of bytes. A program calls read to take some bytes that have arrived from that stream. T C P does not preserve the game’s message boundaries for that call.
One call to read may return:
half of one message;
exactly one message;
one message plus part of the next;
several messages.
Concretely: if the sender writes two length-prefixed messages back to back, the receiver has no say in how they turn up.
Code example. The surrounding prose explains this example; the full lesson contains the exact code.
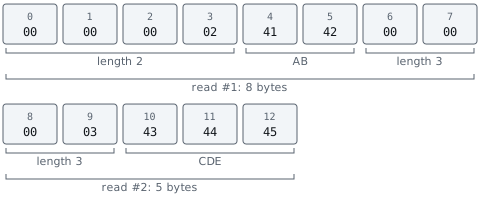
Neither read lands on a message boundary. The receiver has to hold what it has in a buffer, remove complete messages when enough bytes have arrived, and keep the leftover for next time. A parser that assumes one read equals one message works flawlessly over a fast loopback connection while you are testing, then breaks the moment timing changes.
This is why a protocol needs framing.
Code example. The code’s comments explain: Wait for the whole header, even if it arrives across several reads. Check an untrusted size before allocating its payload buffer. A successful result contains one complete payload, without the header.
stream supplies incoming bytes and max_size is the caller’s permitted payload limit. A successful call returns one payload as a Vec<u8>; a truncated header or payload produces an I/O error through ?. For a header 00 00 00 02 followed by 41 42, the returned vector contains just 41 42. The maximum size prevents a bad length field from requesting absurd amounts of memory. This blocking helper also needs an appropriate timeout on a real socket so a peer cannot make it wait indefinitely.
T C P reliability ends at delivering an ordered byte stream to the receiving socket. It does not prove the application parsed a complete message, accepted the request, saved the state, or sent a meaningful reply. The application must provide those guarantees. An acknowledgment can report acceptance, a request ID can identify a repeated request, and a timeout can tell the client when to stop waiting. Decide whether a retry repeats the same request or starts a new one before implementing it.
Section: Byte order is part of the protocol.
The same integer has more than one possible byte order. Decimal 258 is 1 times 256 + 2, so as a four-byte number it has one byte worth 256 (01), one byte worth 1 (02), and two zero bytes. Wesnoth’s four-byte frame length is big endian, which puts the byte worth the most first:
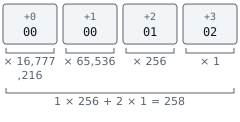
On little-endian x86 memory, a native u32 with the same value would usually appear in the opposite order:
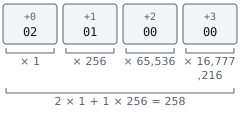
Read with the wrong order, the wire bytes 00 00 01 02 become this value, which is 2 times the large number shown + 1 times 65,536 equals the large number shown: a frame length of more than 33 million bytes. Network code must follow the protocol, not the host C P U, central processing unit,’s default. That is why the reader uses u32::from_be_bytes rather than a pointer cast.
Section: Packets and protocols.
A packet is a chunk of bytes sent across a network. That part is straightforward.
A protocol specifies how programs communicate: how to separate messages, decode their fields, order the conversation, and respond to invalid input. Both programs need matching answers to these four questions:
Where does one message end and the next begin? A T C P connection is one long stream of bytes with no natural gaps, so something has to mark the boundaries.
What is each part of a message? Which bytes are the length, which are the message type, which are the payload, and how each of those is encoded.
Which messages are allowed right now? A login reply makes no sense before a login request. People routinely forget this is part of the protocol at all.
What happens when something is wrong? An unknown message type, a length that does not fit, a message arriving out of turn.
None of that can be worked out by staring at the bytes, because none of it is written in them. Both programs have to know it in advance. That is precisely why reverse engineering a protocol means recovering those four answers — and why a byte layout on its own only ever answers the second one.
📦 Watch for: the same bytes can be perfectly valid at one point in a conversation and meaningless at another. A protocol model has to check when a message is legal, not only what it contains.
A simple framed message might contain:
Code example. The surrounding prose explains this example; the full lesson contains the exact code.
A typed message models the decoded meaning:
Code example. The surrounding prose explains this example; the full lesson contains the exact code.
This enum is a declaration fragment, not a network reader. After framing and validation, a parser can turn a move’s fields into Message::Move with a unit ID and two coordinates; the game logic receives named values instead of raw byte offsets. The bytes are untrusted until parsing succeeds.
Section: One message is wrapped in several layers.
Several layers cooperate when the bot sends one chat message:
Code example. The surrounding prose explains this example; the full lesson contains the exact code.
W M L, Wesnoth Markup Language, is Wesnoth’s own tagged text format for structured data — chat messages, maps, units, and more all get written as bracketed tags such as [message] and [/message] wrapping quoted key="value" fields. It is the serialization format this chapter keeps reversing.
When something fails, ask which layer broke. A correct T C P connection does not prove the W M L is valid. A valid gzip stream does not prove the length prefix used the right byte order.
The receiver undoes the layers in the opposite order, and each step has its own way to fail:

Serialization turns structured values into bytes. Framing tells the receiver where one serialized message ends. Transport moves bytes between endpoints. Keeping those jobs separate makes both the explanation and the code easier to test.

Section: Messages can feed a data pipeline.
A multiplayer service handles more than packets. It may keep durable account and inventory records in a database, reuse expensive results in a cache, and build a search index for queries such as finding a match by region and mode. Those are different access patterns: keep data across restarts, avoid repeating work, and find selected records efficiently. They are not three names for the authoritative state of a running match.
Processing is asynchronous when the sender can continue before the work finishes. A request can enter a queue, then a worker handles it later. A queue acknowledgment might mean “received”; it does not by itself mean “validated, applied, and saved.” The protocol must say which stage each reply confirms.
There are also two common ways to process a sequence of events:
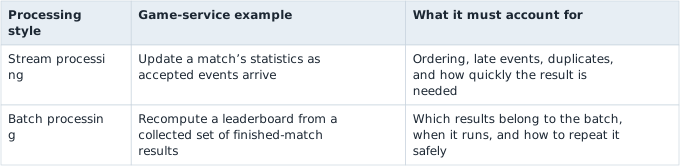
“Stream processing” here means processing ongoing events; it does not mean the T C P byte stream discussed earlier. A service can obtain events from many connections, files, or queues. A batch deliberately waits for a group of data and processes that group together. Neither approach implies that a game can wait for a leaderboard job before processing a player’s movement or damage.
For example, a match event might carry match_id, event_id, and a score change. If a sender retries it after a lost acknowledgment, the receiver must recognise the same event rather than add the score twice. Event identity and retry behaviour belong to the model and protocol, not to whether T C P delivered the underlying bytes correctly.
Bound queues as well as messages: an unbounded queue consumes memory when input arrives faster than it can be processed, and its results grow increasingly stale. Whether a full queue may discard something depends on what the message means, which Lesson 9.7 works through for a relay.
Section: Design the backend for one match.
A player logs in, joins match 42, and buys an item for 300 coins. The game backend is the set of services behind those actions. Separating their jobs explains why a working socket alone cannot prove a successful purchase.
Section: From login to the live world.
Authentication establishes the player’s identity. A session lets later requests refer to that authenticated login; it can outlive one T C P connection. A matchmaker groups compatible players and arranges a match location. It does not calculate their movement. Microsoft’s PlayFab matchmaking overview illustrates that service role.
An A P I, application programming interface, gateway routes requests to the appropriate service. Middleware performs shared checks along that route: validate the session, bound the request, enforce its permissions, and record its outcome. A load balancer can spread these entry requests across equivalent gateway instances. The authoritative match server owns match 42’s accepted positions and damage; route its commands to that owner instead of a randomly chosen empty worker. These are logical jobs, which a small project can combine in one program.
Login, match allocation and asset delivery have different owners. These are logical service roles, not a requirement to deploy every box separately. Choose a tab and step through it to see who answers each request:

Section: Put each value in the right store.
A database keeps structured, durable account balances and inventory. Object storage keeps larger files addressed by keys, such as versioned patches and replay recordings. A cache reuses a result that can be rebuilt; a CDN, or content delivery network, brings eligible asset copies closer to players. An asset cache hit can avoid an origin fetch, as Cloudflare’s request lifecycle explains. Personal account responses need separate authorization and cache rules. A cached lobby count is useful; its old balance must not authorize a new purchase.
Section: One purchase, one effect.
The player has 1,000 coins. Request P7 asks for the 300-coin item. Validate the server’s price and current balance, debit to 700, grant the item, and record P7’s result inside one transaction: either that whole change commits or none does. Concurrent requests also need appropriate isolation or locking; merely surrounding unsafe read-then-write logic with a transaction is insufficient. PostgreSQL’s isolation guide explains these concurrency guarantees and possible transaction retries.
If the reply is lost, retry the same request ID. Idempotency means that repeat has the same effect: return the recorded result, without another debit or item. Scope the ID to its account, reject a changed payload under the same ID, and save the receipt atomically with the effect.
Purchase P7 commits its debit, item and receipt together; retrying P7 returns that receipt. The separate leaderboard example may display an older score until its derived view catches up. The order of the steps is the point, so step through each tab:

Consistency describes which writes a read can observe. A strongly consistent read respects completed writes within its promised scope. A weaker read can return an older replica or cache value. Eventual consistency promises convergence when updates stop and propagation succeeds, not a fixed maximum delay. Currency authorization needs a current protected decision; a leaderboard can tolerate a clearly dated older view. Cosmos DB’s consistency definitions show why these guarantees must be stated explicitly.
Optional: explore the smaller concurrency problem below. Starting at 1,000, a reward of 500 and purchase of 300 should leave 1,200. Overlapping reads and writes can lose one change. Its local lock illustrates ordering; a backend must enforce its database transaction rules across all participating processes.
Section: More matches, with explicit ownership.
Sharding partitions work or records by a key: independent matches can run on different workers. A shared world crossing shard boundaries additionally needs ownership handoffs and ordered cross-boundary actions. Moving a job to another process also adds a message boundary, possible failures, and delay, so start with a small correct local service and distribute work when measurements justify it. Azure’s sharding pattern describes the partitioning tradeoff.
Coordination records which worker owns match 42. On failure, a replacement needs recoverable state and a new ownership generation; an expired worker must be prevented from committing late writes. Electing a replacement alone cannot reconstruct lost match state. Leader-election guidance explains leases and their failure limits. Retried result events also need persistent event IDs to avoid awarding the same win twice.
Section: Spend the latency budget where it matters.
A toy 60-tick-per-second server has about 16.7 milliseconds per simulation step. That budget is distinct from network round-trip delay. Keep slow replay uploads and leaderboard work outside the movement path. Measure queue depth, bytes per player, and slow-tail latency before optimizing. Spatial indexes can reduce repeated full-world searches; smaller state deltas reduce bandwidth, while compression spends C P U time. Extra workers cannot repair an undefined ownership rule or an overloaded shared database.
Section: U D P, user datagram protocol, is made of datagrams.
U D P preserves datagram boundaries but does not guarantee delivery, order, or uniqueness. Fast games often tolerate those tradeoffs for time-sensitive state.
A later position update can make an older one useless, so freshness may matter more than retransmission. In contrast, a one-time inventory change may need explicit ordering and acknowledgment. Choose behavior per message kind instead of labeling an entire game “reliable” or “unreliable.”
Do not assume a game uses only one protocol. It might use T C P for login/chat and U D P for movement.
Section: Ports and sockets.
A socket represents a network endpoint. This complete helper opens a T C P connection to our local test server, or returns an error:
Code example. The code’s comments explain: This bounds connection establishment, not later read/write operations.
127.0.0.1 means the same computer; 15000 selects the server’s listening port. We use loopback and a local test server for this section. A successful result is a connected stream; framing and protocol checks still remain.
Section: Encryption changes what you can see.
If a protocol uses modern encryption correctly, a packet capture shows encrypted bytes, addresses, sizes, and timing—not readable messages. Do not try to defeat encryption or certificate checks.
For learning, use:
your own toy protocol;
a local open-source server;
captured bytes provided by a challenge;
application logs you control.
Section: Captures in this chapter stay local.
The capture, replay, and proxy examples use loopback or a local test server. That keeps timing, state changes, and failures observable while you learn what each protocol layer contributes.
Now that the message boundary and its byte order have a purpose, Lesson 9.3 records a real local exchange and asks which captured bytes correspond to one controlled action.